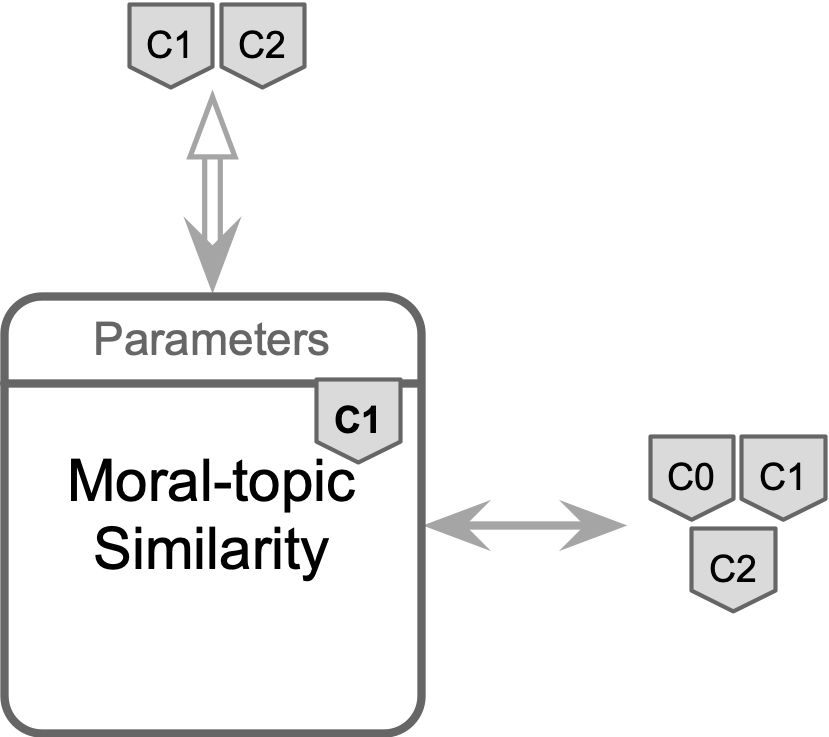
Moral-topic similarity
This component evaluates how desirable a Twitter post is to a user, based on the user’s preferences, in terms of topic and moral values, and on the topics and moral values detected from the post. While topics’ and moral information is provided by other components, such as Topic detection model and MFT values detection, the information and from the user is assumed to be defined as a parameter of the system to be initialised to start the program. This setting is ideal to analyse a system through simulation analyses, as it is possible to fully control the user specifics. Indeed, possible modifications could enable the derivation of user information using collaborative filtering methods. The similarity score is defined by the formula:
where:
-
is the cosine similarity, to measure the affinity of moral and topic content between the user and the item;
-
, with , is the output from a Dirichlet distribution with parameters for , as way to introduce noise to the component inputs that is modulated in magnitude by ;
-
The values and modulates the magnitude of the noise artificially induced to the input variables and respectively;
-
interpolates the importance attributed to the difference between user’s preference and post’s information about topics (larger ) rather than moral values (smaller ).